

Business Continuity vs Disaster Recovery: Differences, Plans, and Testing
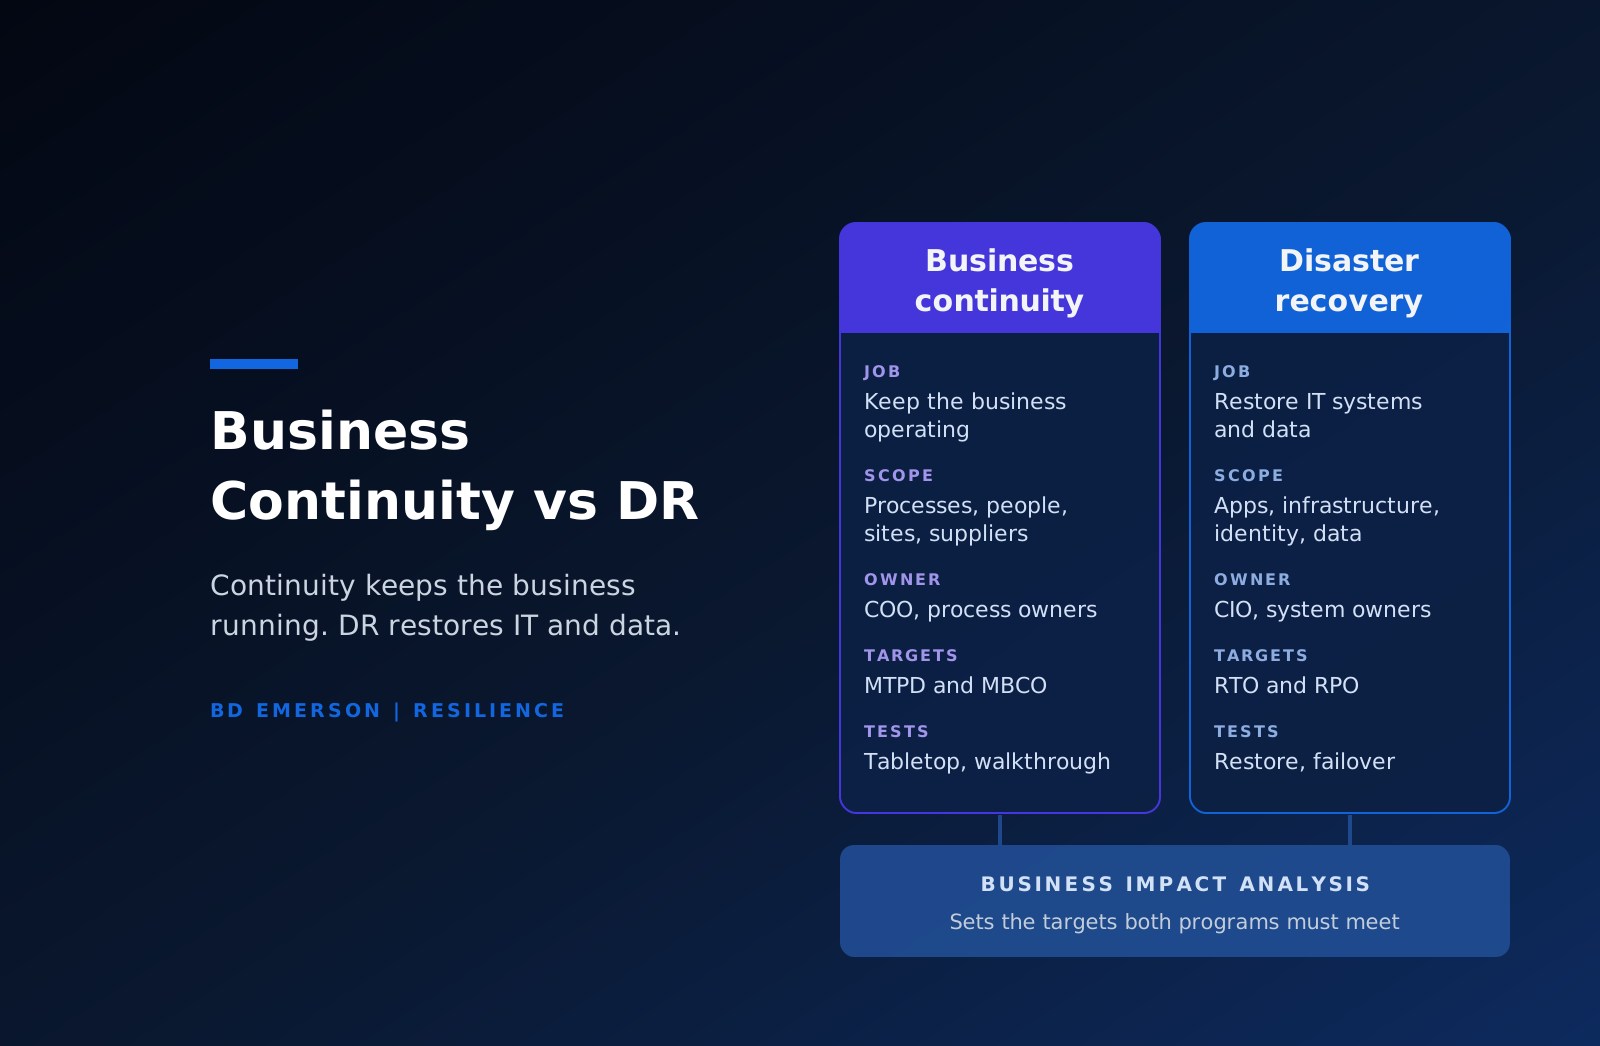
Business continuity keeps the business operating through a disruption; disaster recovery restores the IT systems and data the business runs on. A business continuity program covers people, processes, sites, suppliers, and communications, and it succeeds when each prioritized activity resumes before its maximum tolerable period of disruption (MTPD) runs out. Disaster recovery is the IT part of that program: it brings applications, infrastructure, identity services, and data back within a recovery time objective (RTO) and a recovery point objective (RPO). NIST SP 800-34 Rev. 1 draws the same line, describing the business continuity plan as process-focused and the disaster recovery plan as system-focused. Most companies need both, built from one business impact analysis.
The difference shows up on the first day of an outage. When ransomware encrypts the ERP, the disaster recovery team works to bring it back, while the continuity plan decides how orders get taken, payroll gets run, and customers get told in the meantime. A company with only a disaster recovery plan has a restore queue and no way to operate while it waits, and a company with only a continuity plan has workarounds sized for a four-hour outage that lasts two weeks.
Business continuity vs disaster recovery at a glance
The table compares the two programs on the dimensions auditors and enterprise buyers ask about.
| Dimension | Business continuity | Disaster recovery |
|---|---|---|
| Question it answers | How do we keep delivering our products and services during a disruption? | How do we get the systems and data back? |
| Scope | Prioritized activities and everything they need: people, sites, suppliers, communications, and IT | Applications, infrastructure, identity services, networks, and data |
| Typical owner | COO or business continuity manager, with process owners | CIO or head of infrastructure, with system owners |
| Trigger | Any disruption that threatens a prioritized activity: site loss, staff shortage, supplier failure, or IT outage | Loss of systems or data beyond what normal operations absorb: ransomware, a data center or cloud region outage, a destructive error |
| Objectives | MTPD and minimum business continuity objective (MBCO) for each activity | RTO and RPO for each system |
| Main documents | Business impact analysis, business continuity plan, crisis communications plan | Disaster recovery plan, IT recovery runbooks, backup policy |
| Testing | Tabletop exercises, walkthroughs, alternate-site and remote-work tests | Backup restore tests, partial failover, full failover |
| Standards | ISO 22301:2019, FFIEC Business Continuity Management booklet, DORA Article 11 | NIST SP 800-34 Rev. 1, ISO/IEC 27001:2022 Annex A 5.30, 8.13, and 8.14, DORA Article 12 |
How they connect with incident response and crisis management
Four plans run during a serious cyber disruption, and they overlap in time. Incident response detects, contains, and eradicates the threat; crisis management makes executive decisions and runs communications; disaster recovery restores systems and data; and business continuity keeps prioritized activities running at their minimum level until the systems return. NIST SP 800-34 Rev. 1 describes the hand-off directly: a cyber incident response plan may activate an information system contingency plan or a disaster recovery plan. In ransomware cases the order matters, because restoring systems into an environment the attacker still controls hands them back to the attacker. Figure 1 shows how the four run across an illustrative ransomware disruption.

Three hand-offs decide how that timeline plays out. Crisis management activates the business continuity plan early, because workarounds take hours to stand up and nobody knows yet how long IT will be down. Incident response tells disaster recovery when restoration can start: once the attacker's access is cut and a clean restore point is identified. Disaster recovery then reports restored capacity to the continuity team, so workarounds wind down one process at a time. If your response depends on outside responders, an incident response retainer settles the contract before the first call, and our cyber incident response services page describes how those engagements run.
The documents in each program and who owns them
A BCDR program needs seven core documents, each with one owner. NIST's terms differ slightly from common use: in NIST SP 800-34, recovering a single system is an information system contingency plan (ISCP), and the disaster recovery plan covers relocating system operations to an alternate site after a major disruption. Most companies call both the disaster recovery plan and keep system-level runbooks underneath it.
| Document | What it contains | Typical owner |
|---|---|---|
| Business impact analysis | Prioritized activities with their MTPD, RTO, RPO, MBCO, and dependencies | COO or head of operational risk |
| Business continuity plan | Workarounds, alternate sites, minimum staffing, supplier fallbacks, and activation criteria | Business continuity manager and process owners |
| Crisis communications plan | Spokespeople, approval chain, templates, and notification lists for staff, customers, regulators, and insurers | Head of communications, with legal |
| Incident response plan | Detection, triage, containment, eradication, evidence handling, and escalation | CISO |
| Disaster recovery plan | Recovery strategy, sequence, roles, alternate infrastructure, and each system's RTO and RPO | CIO or head of infrastructure |
| IT recovery runbooks | Step-by-step restore and failover procedures with tested times | System owners |
| Backup policy | Scope, frequency, retention, immutability, and restore testing for each data set | Head of infrastructure |
How RTO and RPO drive disaster recovery design
The RPO decides how often data is copied, and the RTO decides how much standby infrastructure you pay for. A 24-hour RPO can live on nightly backups, while a 15-minute RPO needs snapshots, log shipping, or continuous replication. A 3-day RTO can be met by restoring onto new infrastructure, while a 1-hour RTO needs a running copy somewhere else. AWS's Well-Architected reliability guidance describes four strategies in increasing order of cost and complexity, and the same four apply on premises and in other clouds.
| Strategy | How it works | RPO and RTO (AWS) | Standby run cost (BD Emerson planning range) |
|---|---|---|---|
| Backup and restore | Back up data, then rebuild infrastructure and restore after the event | RPO in hours, RTO in 24 hours or less | Under 10% of the production infrastructure it protects |
| Pilot light | Replicate data and keep core services on, with application servers off until needed | RPO in minutes, RTO in tens of minutes | 10% to 25% |
| Warm standby | Run a scaled-down, fully functional copy of production at all times | RPO in seconds, RTO in minutes | 30% to 60% |
| Multi-site active-active | Serve production from two or more sites at once | RPO near zero, RTO potentially zero | 100% or more |
The cost column is a BD Emerson planning range for standby run cost as a share of the production infrastructure spend it protects, before licensing and staff time. Data volume and retention move the backup figure, replicated database size moves pilot light, the scale-down ratio moves warm standby, and cross-site data transfer and the engineering for write conflicts move active-active. AWS advises against a strategy more stringent than the business needs, because it incurs unnecessary cost. The rule we apply is to pick the cheapest strategy whose tested RTO and RPO beat the BIA target with margin, system by system.
Replication alone does not protect against every disaster. AWS's disaster recovery whitepaper warns that continuous replication can carry corruption or malicious deletion to the standby copy, and that even an active-active design needs point-in-time backups. For data disasters, AWS notes, the recovery point always falls before the moment the disaster was discovered.
Disaster recovery in the ransomware era
Ransomware changes disaster recovery because the attacker goes after the recovery path itself: backups, backup servers, and the identity systems that control them. Three practices decide whether recovery works.
Immutable and offline backups
Keep at least one copy of critical data that production credentials cannot alter or delete. The #StopRansomware Guide from CISA, the FBI, the NSA, and MS-ISAC tells organizations to maintain offline, encrypted backups of critical data and to regularly test their availability and integrity in a disaster recovery scenario. In practice that means object-lock or write-once storage with retention long enough to reach back before the attacker arrived, backup administration on separate credentials outside the production domain, and offline copies of golden images and infrastructure-as-code templates, which the guide also recommends.
Clean-room recovery
Restore into an isolated environment first, prove the restored systems are clean, then reconnect them. A clean room is a segregated network where the team restores backups, scans them for the attacker's tools and persistence, and rebuilds trust before anything touches production. DORA writes the principle into law for EU financial entities: Article 12(3) requires backups restored on the entity's own systems to use ICT systems physically and logically segregated from the source system.
Identity recovery for Active Directory and Entra ID
Recover identity first, because every other system authenticates against it. Microsoft's Active Directory forest recovery guidance recommends backing up at least two writable domain controllers per domain, restoring from a backup taken a few days before the failure, and shutting down all writable domain controllers before the first restored one rejoins production, so compromised data cannot replicate back. Cloud identity needs its own plan. Microsoft documents that Entra ID soft-deletes users, Microsoft 365 groups, cloud security groups, and applications for 30 days and hard-deletes other object types immediately, and it recommends keeping a known-good copy of tenant configuration, such as Conditional Access policies, in an external versioned repository.
How to test business continuity and disaster recovery plans
Test both programs on a schedule, because each test type proves something different. FEMA's HSEEP doctrine (January 2020) splits exercises into discussion-based types, such as tabletop exercises, and operations-based types, such as drills, functional exercises, and full-scale exercises. NIST SP 800-84 applies the same tabletop and functional distinction to IT plans. The cadence column is our recommendation.
| Test type | What happens | What it proves | Recommended cadence |
|---|---|---|---|
| Tabletop exercise | A facilitator presents a scenario and leaders talk through each decision | Roles, escalation, and communications work | Twice a year: one cyber scenario, one operational |
| Walkthrough | Each plan owner steps through the procedure with the people who would run it | The plan is current and executable as written | Annually and after major changes |
| Simulation (functional exercise) | Teams perform their functions in real time in a simulated environment | Teams can execute under time pressure | Annually for prioritized activities |
| Backup restore test | IT restores a system or data set and checks integrity and completeness | Backups are usable and the RPO is real | Quarterly for systems behind prioritized activities |
| Partial failover | One system or site fails over and carries production traffic | A single RTO is achievable | Annually for systems with RTOs under 24 hours |
| Full failover | Production runs from the recovery environment for a set period | The whole recovery sequence meets its RTOs | Every one to two years where the BIA justifies the cost |
Frameworks set minimums and mostly leave the interval to you. DORA Article 11(6) requires EU financial entities to test ICT business continuity plans and ICT response and recovery plans at least yearly and after substantive changes to systems supporting critical or important functions. ISO 22301:2019 clause 8.5 requires exercises at planned intervals and after significant changes, HIPAA treats testing and revision of contingency plans as addressable, and SOC 2 criterion A1.3 requires recovery plan procedures to be tested, with a point of focus on the integrity and completeness of backup data. A tabletop exercise built from the BIA's worst-timed scenario tests both programs at once, and our list of tabletop exercise scenarios gives starting points.
What SOC 2, ISO 27001, HIPAA, and DORA require
All four frameworks require backup, recovery, and testing, and they differ in how much continuity planning they require beyond IT. The table summarizes the requirements as of October 2026.
| Framework | Continuity | Recovery and backup | Testing |
|---|---|---|---|
| SOC 2 Trust Services Criteria (2017, revised points of focus 2022) | CC9.1: mitigate risks from potential business disruptions | CC7.5: recover from identified security incidents; A1.2: backup processes and recovery infrastructure | A1.3: test recovery plan procedures |
| ISO/IEC 27001:2022 | A 5.29: maintain information security during disruption | A 5.30: ICT readiness for business continuity; A 8.13: backups maintained and regularly tested; A 8.14: redundancy that meets availability requirements | Required by 5.30 and 8.13 |
| HIPAA Security Rule, 45 CFR 164.308(a)(7) | Emergency mode operation plan (required); applications and data criticality analysis (addressable) | Data backup plan and disaster recovery plan (both required) | Testing and revision procedures (addressable) |
| DORA, Regulation (EU) 2022/2554 | Article 11: ICT business continuity policy, BIA, and a crisis management function for entities other than microenterprises | Article 12: backup policies, segregated restoration, redundant capacity, and RTOs and RPOs per function | Article 11(6): at least yearly |
Two notes on that table. The SOC 2 Availability criteria apply only when Availability is in scope of the examination, while CC7.5 and CC9.1 are common criteria that apply to every SOC 2 report. BD Emerson performs SOC 2 examinations through its CPA attest practice and also builds continuity programs in readiness work, and the independence line holds: the firm that examines your controls does not also implement them. For HIPAA, HHS proposed on January 6, 2025 to require written procedures to restore certain systems and data within 72 hours. As of October 2026 the proposal is not final, so the current text of 45 CFR 164.308(a)(7) still governs.
Which should a small or mid-size company build first?
Build disaster recovery first for any system whose tested restore time is longer than the MTPD of a process that depends on it, and build business continuity first everywhere else. The rule needs two inputs, a short BIA and one real restore test per critical system, and both fit in the first month. If the restore test shows the ERP takes four days to come back and order processing has a 48-hour MTPD, the money goes to the ERP's recovery design, because no workaround holds for four days. If every critical system restores well inside its MTPD, the gap sits on the business side, and the continuity plan, the crisis communications plan, and a tabletop exercise come first.
For a company building both for the first time, we sequence the work over about 90 days. Weeks 1 to 4 cover a BIA of the top 10 to 15 processes and a restore test of each system they depend on. Weeks 5 to 8 add immutable backups wherever the test failed, the crisis communications plan, and the incident response plan. Weeks 9 to 12 deliver disaster recovery runbooks for the systems with the tightest RTOs, the business continuity plan for the top processes, and a tabletop exercise that tests both. These are BD Emerson planning ranges, and the number of sites, the state of the backups, and process owner availability move them most. A virtual CISO engagement is the usual home for this work at companies without a full-time continuity manager, and the method for the first step is in our business impact analysis guide.
Frequently asked questions
Is disaster recovery part of business continuity? Yes. Disaster recovery is the IT component of a business continuity program. Business continuity covers everything a prioritized activity needs, including people, sites, suppliers, and communications, while disaster recovery restores systems and data within the RTOs and RPOs the business impact analysis sets. NIST SP 800-34 Rev. 1 reflects the split by describing the business continuity plan as process-focused and the disaster recovery plan as system-focused.
What does BCDR stand for? BCDR stands for business continuity and disaster recovery, the combined program that keeps a business operating through a disruption and restores its technology afterward. Companies use the term when one team or one document set covers both: the business impact analysis, the continuity plan, the crisis communications plan, the disaster recovery plan, and the IT recovery runbooks.
What is the difference between a business continuity plan and a disaster recovery plan? A business continuity plan explains how each prioritized activity keeps running during a disruption: workarounds, alternate locations, minimum staffing, supplier fallbacks, and who activates the plan. A disaster recovery plan explains how IT restores systems and data: the recovery sequence, standby infrastructure, runbooks, and each system's RTO and RPO. The continuity plan assumes the recovery plan's tested times, so the two must agree.
Who owns business continuity and who owns disaster recovery? Business continuity usually sits with the COO, a chief risk officer, or a business continuity manager, with each process owner responsible for their part of the plan. Disaster recovery sits with the CIO or head of infrastructure, with system owners responsible for runbooks and restore tests. One executive should approve the business impact analysis, because its RTOs and RPOs bind both programs.
How often should you test a disaster recovery plan? We recommend restore tests at least quarterly for systems that support prioritized activities, a failover test at least once a year for systems with RTOs under 24 hours, and a tabletop exercise on the full plan twice a year. DORA requires EU financial entities to test at least yearly, and ISO 22301 requires exercises at planned intervals and after significant changes.
Does SOC 2 require a disaster recovery plan? SOC 2 requires recovery capability, and a disaster recovery plan is the usual evidence. Common criterion CC7.5 requires activities to recover from identified security incidents in every SOC 2 report, and when Availability is in scope, A1.2 covers backup processes and recovery infrastructure and A1.3 requires recovery plan procedures to be tested. In a Type 2 report, a recovery test the controls promise but the company never ran is an exception.
If you are building BCDR for the first time or need it to hold up in a SOC 2, ISO 27001, or HIPAA review, our virtual CISO team can run the business impact analysis, write the continuity and recovery plans, and test both in a tabletop exercise with your leadership team.

About the author












